
What is DynamoDB? A practical introduction
Written by Rafal Wilinski
Last updated: October 23rd, 2026
Amazon DynamoDB is AWS's fully managed, serverless NoSQL database for key-value and document workloads. You create tables and read or write items through an API while AWS manages storage, replication and infrastructure. It is designed for predictable operational access patterns, such as retrieving a shopping cart or a customer's orders, with on-demand or provisioned pricing and optional global replication.
Why use DynamoDB?
DynamoDB removes the need to size database servers, maintain database software or manage connection pools. Applications access it through AWS SDKs, the CLI or HTTP APIs. A small application can use the same service as a high-traffic one, but its keys and indexes still need to support the way the application reads and writes data.
Its main benefits are managed operations, key-based access, flexible item structures and integration with other AWS services. You can react to changes through Streams, expire records with Time to Live, protect data with backups, and replicate tables across Regions. These are useful building blocks, not a guarantee that every workload will be cheap or automatically scale without design work.
The service works well with AWS Lambda, but it is also available to containers, virtual machines and applications outside AWS. In any environment, use an AWS identity with appropriate permissions and account for network latency between the application and the database.
Table of contents
- Key facts
- History
- Anatomy and operations
- Feature updates
- When to use DynamoDB
- When not to use DynamoDB
- Twelve common misconceptions
- Frequently asked questions
- Resources
Amazon DynamoDB key facts
| Property | What to know |
|---|---|
| Database model | NoSQL key-value and document database |
| Operator | Amazon Web Services |
| Initial release | January 18, 2012 |
| Deployment | Managed AWS service; DynamoDB Local is for development and testing |
| Open source | The managed DynamoDB service is not open source |
| Data schema | Fixed primary-key schema, flexible non-key attributes |
| Query interfaces | DynamoDB APIs and SQL-compatible PartiQL |
| Main SDK options | JavaScript/TypeScript, Python, Java, .NET, Go and other AWS-supported languages |
| Read consistency | Eventual by default; strong reads available for tables and LSIs, not GSIs |
| Transactions | ACID operations within an account and Region; unavailable on MRSC global tables |
| Replication | Across Availability Zones by default; optional multi-Region global tables |
| Capacity modes | On-demand or provisioned, with optional auto scaling in provisioned mode |
| Encryption | Always on at rest; HTTPS protects API traffic in transit |
| Backups | On-demand backups and configurable point-in-time recovery |
| Change processing | DynamoDB Streams and integrations with other services |
| Caching | Optional DynamoDB Accelerator (DAX) |
| Monitoring | CloudWatch, Contributor Insights and API diagnostics |
| Item size | Up to 400 KB, including attribute names and values |
“DDB” is a common abbreviation for DynamoDB in AWS code and discussions. It does not indicate a separate database product or engine. The table above describes the managed service; local development tools have different operational capabilities and do not prove production performance.
DynamoDB's history
Amazon's 2007 Dynamo paper described a highly available key-value storage system built for its distributed services. It explained tradeoffs around availability, replication and consistency when individual machines fail. Those ideas influenced the broader distributed-database field.
AWS launched DynamoDB on January 18, 2012 as a managed database service. Dynamo and DynamoDB are related historically, but the paper is not a specification of today's DynamoDB API or consistency modes; the DynamoDB paper guide compares the two designs. Use current documentation when designing an application.
The service has since expanded beyond basic item access to include secondary indexes, transactions, global tables, backup and recovery, data integrations and vector search. Because AWS runs the managed service, customers do not upgrade a database engine version to receive those capabilities. SDKs, local tools and infrastructure providers still have versions and may need updates before they can configure a new feature.
Anatomy of DynamoDB
DynamoDB stores data in tables. A table contains items, and each item contains named attributes. Attributes can hold scalar values, nested maps and lists, or sets. Items can differ in shape as long as they satisfy the table and index key requirements.
A customer profile could contain a name and contact settings, while an order item contains line items and a shipping address. They may live in separate tables or share one table with a deliberate key convention. DynamoDB does not require one table per entity type, and it does not require a single-table design either.
Primary keys and indexes
A simple primary key contains one partition-key attribute. A composite primary key contains a partition key and a sort key. The complete primary key is unique within a table. A sort key lets you keep a collection of related records under one partition-key value and retrieve ranges or prefixes within it.
For example, customerId = CUSTOMER#42 and orderId = ORDER#100 identify one order. Querying CUSTOMER#42 retrieves that customer's collection. The key-design overview explains how the choice determines access patterns.
Secondary indexes provide alternate lookups. A GSI can organize those orders by seller instead of customer. An LSI retains the table's partition key but supplies a different sort key. Indexes store additional data and add write work, so create them for specific queries. The index comparison covers consistency, projections and limits.
Reads, writes and query behavior
PutItem writes or replaces one item. GetItem reads by full primary key. UpdateItem changes selected attributes, and DeleteItem removes one item. Conditions let a write depend on an expected state, such as an item being absent or a version number matching.
Query selects one partition-key value, optionally with a sort-key condition. Scan reads broadly across a table or index. Filters run after reading and do not refund read capacity for discarded items. Both operations paginate, so the first response is not necessarily the complete result.
PartiQL offers SQL-compatible statements for these operations. It does not add a general-purpose relational query optimizer, cross-table joins or free scans. Knowing the key and the underlying access path remains necessary even when the statement resembles SQL.
Storage and partitioning
AWS manages physical partitions and replicates data across Availability Zones. You do not select servers or place individual partitions. DynamoDB can grow a table and redistribute work, while key design determines whether requests can be distributed effectively.
A table with many records can still suffer from a hot key if most traffic targets one item or collection. A GSI can be hot even when the base table is well distributed. On-demand capacity and adaptive capacity help with changing workloads, but neither removes partition-level limits or application-level contention.
Consistency, transactions and global tables
Ordinary reads are eventually consistent by default. A successful write is durable, but an immediate eventual read may return older data. Where supported, request a strongly consistent read when correctness requires the latest committed value. GSIs are always eventually consistent, including on strongly consistent global tables.
Transactions group reads or writes atomically within an AWS account and Region. They are useful for coordinated changes such as reserving inventory and creating an order. Conditional writes are often enough for simpler single-item requirements and have a different cost profile.
Global tables replicate data across Regions. Multi-Region eventual consistency (MREC) propagates changes asynchronously and resolves concurrent item changes using last-writer-wins behavior. A transaction on an MREC table is atomic in its originating Region, but its changes do not replicate as one atomic unit.
Multi-Region strong consistency (MRSC) provides strongly consistent reads across its replicas and synchronously replicates writes before acknowledging them. It requires three Regions, using three replicas or two replicas and a witness, and has feature restrictions including no transactions, TTL or LSIs. Choose consistency from application requirements; it changes latency and available features. The global tables guide covers the deployment choices.
What DynamoDB costs
In on-demand mode, you pay for read and write request units plus storage and any enabled additional features. In provisioned mode, you pay for configured read and write capacity, whether or not you use all of it. Provisioned auto scaling adjusts that configuration within your chosen bounds.
Since the price reduction effective November 1, 2024, Standard-class on-demand rates in US East (N. Virginia) are $0.625 per million write request units and $0.125 per million read request units. Standard storage is $0.25 per GB-month, before applicable free-tier storage. Prices depend on Region and table class; use the official pricing page for a quote.
A request unit is not always one application request. Ordinary writes round up by 1 KB, and strongly consistent reads by 4 KB; eventual reads use half the corresponding read units. Transactions, indexes and global replicas can add work. Large items, broad scans or frequent projected-field updates therefore change the bill even when the number of application calls stays constant.
The always-free Standard allowances include 25 GB of storage and 25 provisioned read and write capacity units per Region per payer account. The provisioned allowance is not an allowance of free on-demand reads and writes. New-account credits are separate and depend on the AWS Free Tier plan.
An idle on-demand table can still incur storage, backup and other feature charges. DAX has its own running cost. Standard-IA lowers storage prices but raises throughput prices, so it suits storage-heavy workloads rather than every infrequently used application. Database Savings Plans and reserved-capacity options also exist for eligible usage; commitment discounts should follow a measured workload.
On-demand is the default and AWS-recommended capacity option for most workloads. Provisioned capacity can still be economical for steady, well-utilized demand. Warm throughput shows capacity available immediately and supports paid pre-warming for expected spikes. Optional on-demand maximum-throughput settings can throttle excess traffic, but are not a guaranteed hard spending ceiling. Model the workload with the DynamoDB pricing calculator before comparing database costs.
Built-in operational features
Streams. A stream records item changes for 24 hours and can trigger Lambda or other consumers. Records for one item retain their change order, while a consumer must handle retries and duplicate delivery. This supports notifications, audit pipelines and derived views. The Streams guide covers configuration and failure handling.
Time to Live. TTL deletes expired items asynchronously, typically within a few days. It is useful for sessions and transient records, but is not an exact expiration scheduler. Applications must stop treating an expired record as valid before the background deletion occurs. Replicated TTL deletes in global tables can incur write charges in other Regions.
Backups and recovery. On-demand backups preserve a table for later restoration. Point-in-time recovery provides per-second restore points over a configured window of 1 to 35 days, defaulting to 35. Restore creates a new table, so recovery also involves application routing and rechecking settings. Shortening the PITR window does not lower its price.
Import and export. Bulk import from S3 creates a new table from supported formats. Export to S3 uses PITR data without consuming table read capacity; full, incremental and filtered exports support different extraction needs. S3 charges and the operation's own charges still apply.
Caching. DAX is an optional managed cache for supported DynamoDB read patterns. It can reduce latency for cacheable reads, but introduces its own capacity, cost and consistency considerations. It is not a remedy for a data model that repeatedly scans a large table.
Security and governance. Encryption at rest is always enabled. IAM controls API access, resource-based policies can grant access to tables and streams, and tag-based access control supports broader governance patterns. Private connectivity options include VPC endpoints. Applications still need least-privilege roles, protected credentials and appropriate data handling.
Analytics and search. Managed zero-ETL integrations can feed Amazon Redshift, OpenSearch and lakehouse destinations without maintaining a custom extraction pipeline. Destination compute, freshness and supported data shapes still matter. Native vector indexes provide another search path for embeddings, separate from ordinary GSI key queries.
DynamoDB updates and feature releases
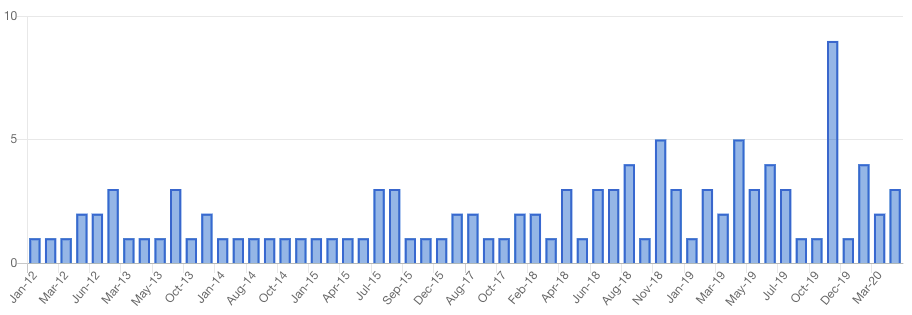
The chart below records earlier releases. It is historical context, not a complete list of current capabilities.
| Period | Changes that affect application design |
|---|---|
| 2023 | Deletion protection, incremental export to S3 and the OpenSearch zero-ETL integration |
| 2024 | Resource-based policies, PrivateLink access, configurable on-demand maximum throughput, warm throughput and lower on-demand prices |
| 2025 | Configurable PITR windows, generally available MRSC global tables, multi-attribute GSI keys and Database Savings Plans |
| 2026 | Multi-account global tables, native vector search, expanded MRSC Region combinations, filtered exports and the ability to disassociate an MREC replica |
Two changes deserve particular attention when reading older tutorials. GSIs now support up to four native partition-key attributes and four sort-key attributes, reducing the need to concatenate fields solely for an index. Base-table keys are unchanged.
Native vector search became generally available in August 2026. On-demand tables can maintain vector indexes and use SearchVectors for approximate nearest-neighbor search. It is eventually consistent, has separate pricing and quotas, and does not make ordinary Query perform similarity search. Your application still needs an embedding model and an indexing strategy. The vector search guide walks through an end-to-end example.
For migrations, check the current feature documentation rather than assuming a newly available feature applies to every consistency mode, Region or local emulator. The DynamoDB document history provides a maintained change log.
When to use DynamoDB
DynamoDB fits operational data when the application can state its important reads and writes ahead of time. Common examples include:
- Shopping carts and customer orders: retrieve a customer collection, update individual items and coordinate writes when needed.
- Sessions and short-lived state: direct token or user lookup, with application-enforced expiry and TTL cleanup.
- Metadata and profiles: small records fetched by stable identifiers, with optional alternate lookup indexes.
- Device events and time-series data: bounded time buckets and distributed writes, with a separate plan for analytics and retention.
- Leaderboards and workflow queues: explicit ranking or state indexes designed for expected traffic.
- Relationship data: adjacency-list items supporting known forward and reverse lookups, rather than arbitrary graph traversal.
- Event-driven applications: Streams consumers maintain notifications, aggregates or downstream systems.
- Location-oriented records: application-defined geohash access patterns where their query tradeoffs fit, rather than assuming native spatial SQL.
It is especially attractive when managed infrastructure and AWS integration reduce operational work. A workload with unpredictable traffic can benefit from on-demand billing, provided its hot keys, immediate throughput and quotas have been considered. Prototype with representative data and skewed traffic, not only a handful of evenly distributed test records.
When not to use DynamoDB
Choose a relational database when changing joins, constraints and ad hoc relational queries are central to the product. DynamoDB can model relationships, but application-managed denormalization and indexes may be unnecessary complexity for that workload.
Choose object storage for large files and blobs. DynamoDB can store Binary attributes, but its 400 KB item limit makes it a poor home for videos or large documents. A common design stores metadata and an object reference in the table.
Choose an analytical system for broad aggregations and exploratory reporting, or feed one through an integration. DynamoDB is optimized for operational access rather than repeated table-wide scans. Native vector search also does not replace every full-text, spatial or analytical search capability.
Finally, account for application location and portability. An application outside AWS can use DynamoDB, but network latency, transfer cost and dependency on AWS APIs may affect the decision. DynamoDB Local is useful for development, not a self-hosted production edition of the managed service. DynamoDB alternatives compares the main options.
Twelve common DynamoDB misconceptions
1. NoSQL cannot represent relationships
Relationships can be represented with item collections, adjacency lists and secondary indexes. What changes is where the work happens: you design access paths and sometimes duplicate data instead of relying on a relational join at read time. Referential integrity is generally an application responsibility.
Single-table design is one technique, not a prerequisite or a marker of project maturity. Separate tables can be clearer when access patterns, ownership or lifecycle differ. Tools and frameworks can help describe a model, but they do not remove its underlying consistency and query tradeoffs.
2. DynamoDB is always slow, or always equally fast
Neither claim is useful without a workload. Network distance, request size, access pattern, consistency, client retries and contention all affect observed latency. AWS designs the service for low-latency key-based operations; that does not guarantee the same end-to-end response time for every request.
Measure latency from the actual application environment and inspect percentile behavior under realistic load. A paginated scan, an exact key lookup and a cross-Region synchronous write are different operations, even if all are called “database requests.”
3. DynamoDB is always expensive
Cost depends on item sizes, request volume, indexes, capacity mode and optional features. A workload that reads small items by key can have a very different bill from one that repeatedly scans and filters. Compare the current prices, including the on-demand reduction, rather than figures from an old tutorial.
Also compare operational effort, but do not assume managed means universally cheaper. A well-utilized existing relational database may be an economical choice. Model the actual queries, storage and maintenance work on both sides.
4. Schemaless means no schema decisions
DynamoDB fixes the primary-key schema and enforces types on index keys. Non-key attributes are flexible, but applications still need contracts for names, types, optional fields and versions. Otherwise, a field written as a Number by one writer and a String by another can break application logic or a future index.
Treat validation and migrations as application work. A schema explorer or sample scan shows observed data; it does not prove every item satisfies the intended contract.
5. A small API makes data modeling trivial
The item APIs are approachable, and SDKs handle request signing and serialization. The harder work is often choosing a key that makes the important collection query efficient while distributing writes. Adding another filter does not repair a missing access path.
Start with concrete reads and writes, model sample items, then test pagination, conditional writes and skewed traffic. Libraries such as Dynamoose or DynamoDB Toolbox can reduce application boilerplate, but their abstractions still operate within DynamoDB's rules. Keep SDK and library versions supported.
6. SQL syntax makes it a relational database
PartiQL supports SQL-compatible data statements. It does not turn DynamoDB into PostgreSQL or supply arbitrary joins and relational constraints. A statement without a useful key condition can still require a scan.
Use PartiQL when its syntax improves clarity, and inspect how it reaches the data. Selecting every item from a large table remains a broad operation regardless of how concise the statement looks. The underlying key model and capacity accounting remain the same.
7. DynamoDB only works with serverless compute
Lambda is a common companion, but applications running on EC2, containers, workstations or other networks can call the same service. Requests require authorization and reachable endpoints, not a particular compute platform.
Choose the credential mechanism for that environment, usually a role in AWS and an appropriate temporary-credential workflow elsewhere. Long-lived access keys embedded in source code are unnecessary for the examples in current AWS SDKs and create avoidable operational problems.
8. Fully managed means nothing needs operating
AWS handles database servers, replication infrastructure and service maintenance. Your team still owns capacity choices, index design, retry behavior, alarms, recovery procedures and application failures. A restored table also needs an intentional cutover to become the application's active database.
Monitor table and index health together. A GSI that cannot absorb propagated writes can throttle base-table writes, so looking only at total table capacity can miss the cause. Test restore and failure scenarios before they become urgent.
9. Encryption makes every application secure
Encryption at rest is automatic, but it does not correct overly broad permissions or inappropriate data storage. Resource-based policies, identity policies and tag-based controls need to express the intended access boundary. Audit access and protect credentials.
Backup settings and deletion protection also need explicit choices. They serve different purposes: backups help recover data, while deletion protection blocks a table deletion until disabled. Neither replaces the application's responsibility to control who can read or modify sensitive records.
10. DynamoDB is unsuitable for serious production systems
DynamoDB is used for production operational workloads, including Amazon's own systems. The relevant question is whether its access model and operational behavior fit your application, not whether a particular customer once stored a headline number of records.
Evaluate durability, consistency, recovery and availability requirements directly. Service-level agreements have conditions, and a global-table deployment needs an application failover plan. A database choice is stronger when it is supported by representative tests and a recovery procedure than by customer anecdotes.
11. DynamoDB only makes sense at huge scale
Small applications can use it without provisioning database machines. On-demand billing can suit intermittent use, and free-tier allowances can help during development. Small scale is not a reason to reject the service.
It is also not a reason to ignore costs: stored data, backups and optional features can continue billing while requests are quiet. Keep development tables identifiable and remove resources intentionally when they are no longer required. Choose the simplest model that answers the application's queries.
12. DynamoDB data cannot support analytics
DynamoDB is not a general-purpose analytical engine, but its data can feed one. Zero-ETL integrations with Redshift and lakehouse destinations provide managed paths for reporting; OpenSearch integration supports richer search. Integration freshness and destination costs are part of the design.
Streams-based consumers can also maintain selected aggregates for operational reads. Such consumers need idempotency and failure recovery, and their results may lag behind source writes. Avoid claiming that a derived dashboard is always current merely because it is event-driven.
Frequently Asked Questions
What is Amazon DynamoDB, and what does DDB mean?
Is DynamoDB SQL or NoSQL?
Is DynamoDB a document database?
How is data stored in DynamoDB?
Does DynamoDB support strong consistency and transactions?
Is DynamoDB good for unstructured data?
Additional DynamoDB resources
To try it hands-on without an AWS account, follow the DynamoDB tutorial for beginners. Use the DynamoDB tutorials for focused implementation guides, and the AWS Developer Guide for current service behavior. Start with one access pattern, model its keys and returned data, and measure it before extending the design.
Dynobase is a Professional GUI Client for DynamoDB
Start your 7-day free trial today