
DynamoDB Joins: Modeling and Querying Related Data
Written by Lakindu Hewawasam
Last updated: October 23rd, 2026
DynamoDB does not execute SQL JOIN operations, including through its PartiQL interface. You can read related entities together by modeling them in an item collection, combine separate reads in your application, or move data into an analytics engine that supports joins. A single-table Query returns stored items; your application still assembles the organization, users or other related objects into the response it needs.
Choose where the relationship is resolved
| Approach | Useful when | Main tradeoff |
|---|---|---|
| Item collection in one table | Related entities are commonly fetched together | Key design must match the access pattern |
| Application-side join | Entities have independent storage or lifecycle requirements | More reads and explicit consistency handling |
| Denormalized attributes or a read model | A stable combined view is read frequently | Duplicated values need an update policy |
| Analytics engine | Questions require ad hoc joins and aggregations | Data movement, freshness and analytics charges |
Single-table design is one option, not a requirement for every application. Multiple tables can be appropriate when entities have different operational needs or are rarely read together. AWS's relational-data modeling example discusses grouping data around access patterns and using separate tables when appropriate.
Model an organization and its users
Keep the original example's relationship: an organization has many users, and each user belongs to one organization. The table is test-application, with String partition key PK and String sort key SK.
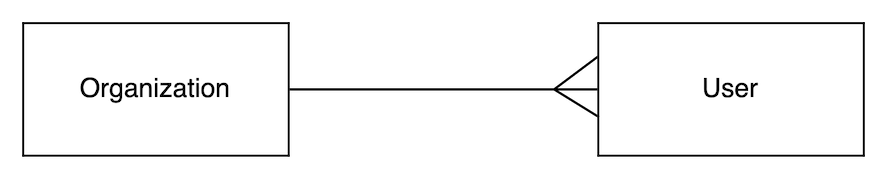
Store the organization profile and its users under the same partition-key value:
| PK | SK | Entity type | Example attributes |
|---|---|---|---|
ORG#APPLE | ORG#APPLE | organization | name: Apple |
ORG#APPLE | USER#LAKINDU | user | name: Lakindu, role: admin |
ORG#APPLE | USER#ALEX | user | name: Alex, role: member |
ORG#MICROSOFT | ORG#MICROSOFT | organization | name: Microsoft |
These are illustrative records, not claims about those companies' systems. In production, stable IDs are usually better key components than names because names can change. The ORG# and USER# prefixes are application conventions, not special DynamoDB syntax. Uniqueness comes from the combination of PK and SK.
The organization profile is an ordinary item whose sort key repeats its partition key. A user's sort key identifies that user within the organization. An entityType field is useful for application dispatch and inspection, but the query patterns below use keys rather than filtering on that field.
Define the model and access patterns
The following screenshots are from the original walkthrough and illustrate the key layout. They show an older editor interface; the textual schema and SDK v3 examples are the current instructions. Dynobase's data modeling workspace supports planning single-table access patterns and indexes.
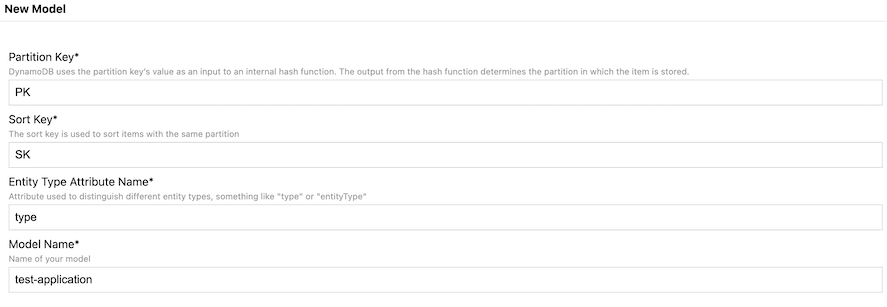
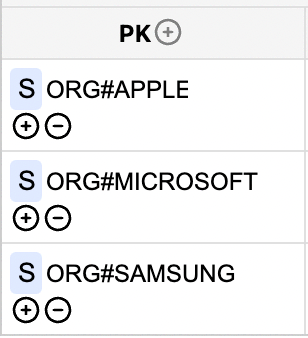
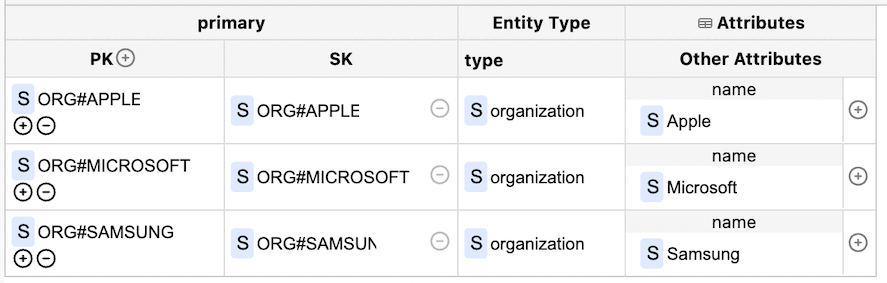
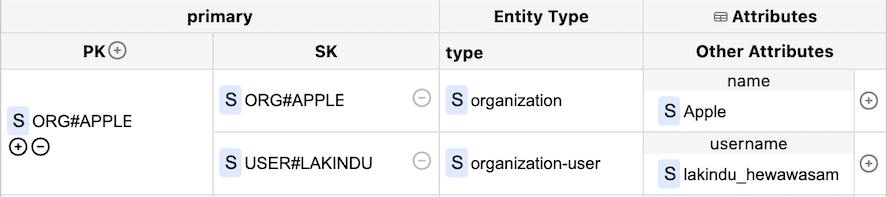
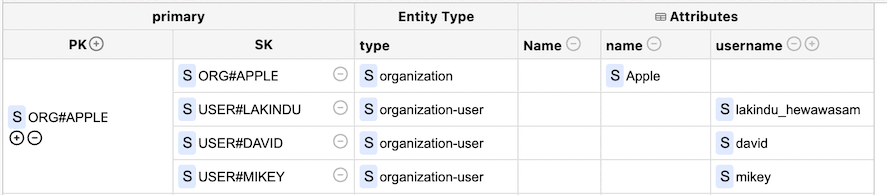
The layout supports four distinct reads:
- Get the organization profile by its complete key.
- Query user items with the organization's
PKand aUSER#sort-key prefix. - Get one user by the organization and user keys.
- Query the whole organization collection, including its profile and users.
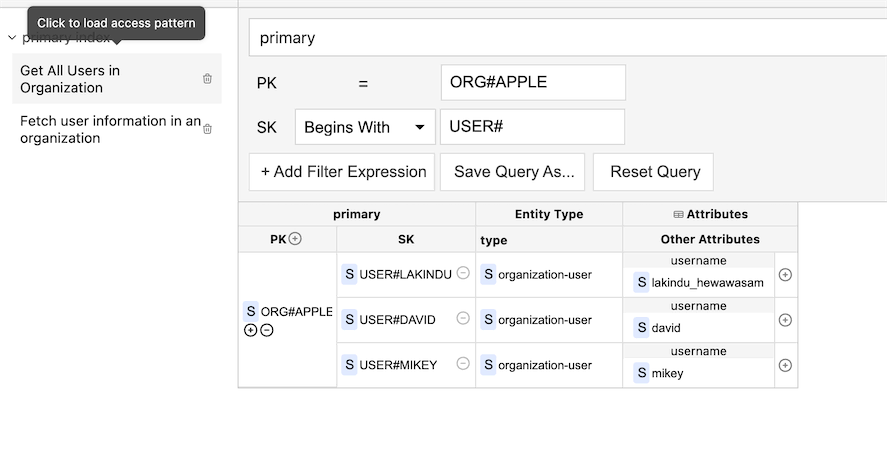
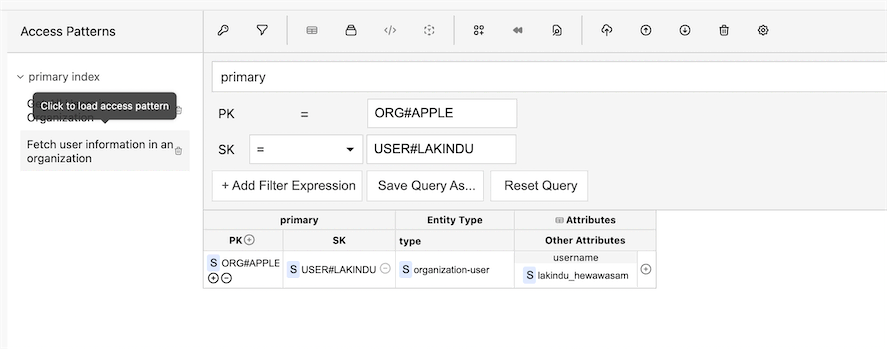
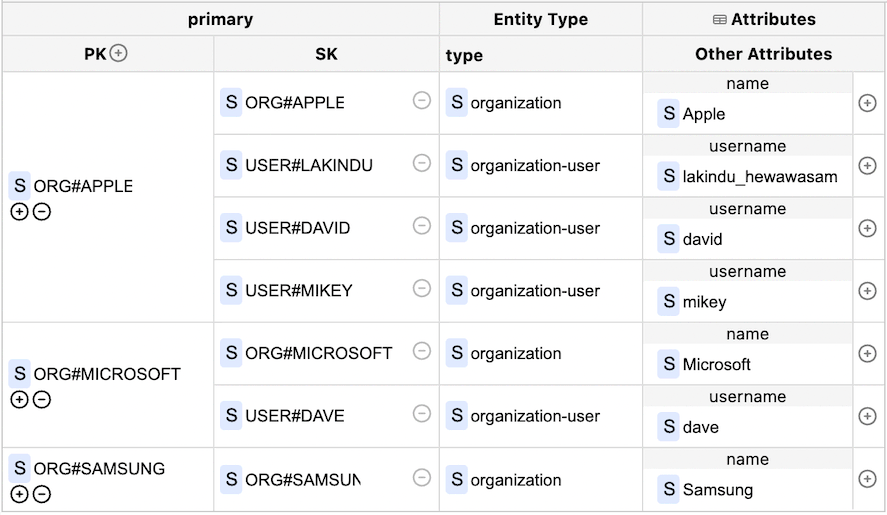
Sharing a partition-key value creates a logical item collection. It is not a promise that all of its data remains on one physical partition. Avoid making a correctness or latency assumption depend on physical co-location.
Querying the modeled data with SDK v3
Install @aws-sdk/client-dynamodb and @aws-sdk/lib-dynamodb, configure AWS credentials and a Region, and use an ES module. The examples assume the sample records already exist.
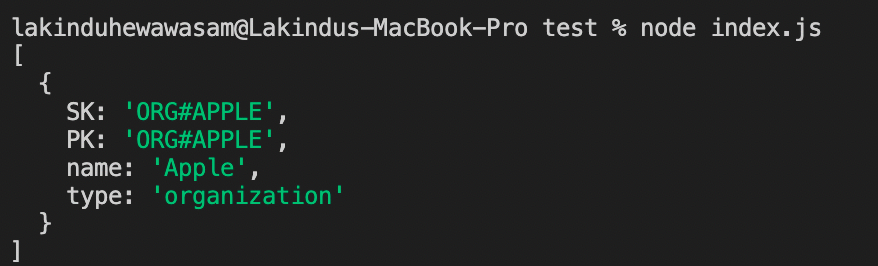
Querying organization information
When the whole primary key is known, GetItem is the direct lookup. The document client names this command GetCommand:
A Query with equality on both keys can retrieve the same item, but adds no benefit here. The result is one stored profile, not a profile joined with every user.
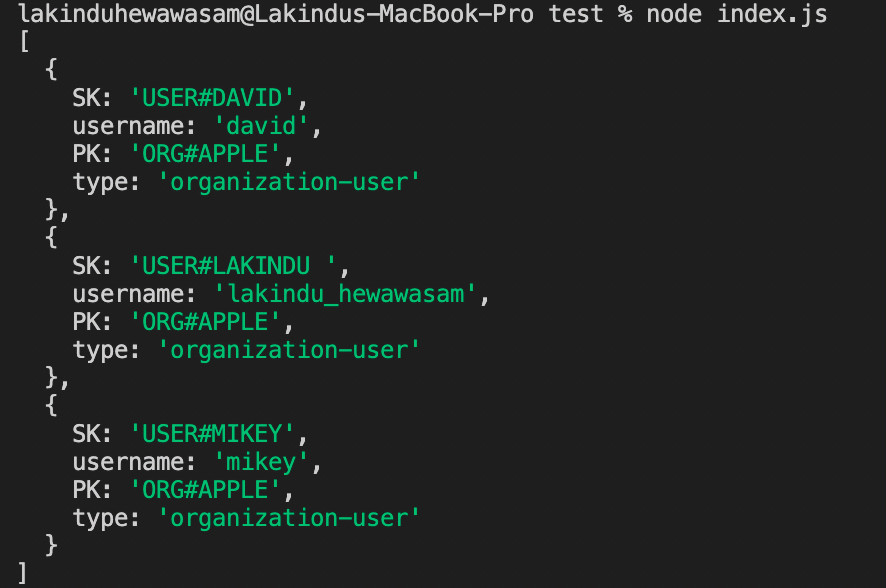
Fetching all users in an organization
Query the USER# sort-key prefix and paginate the results:
The sort-key condition selects user items before reading the result range. It does not return the organization profile because that item's SK begins with ORG#. Use Query vs Scan to understand why this key-based selection differs from filtering a table scan.
Fetching one user in an organization
Both key values are required. If a user moves to a different organization, its key changes, so model that as a coordinated delete and put rather than an update to the existing key.
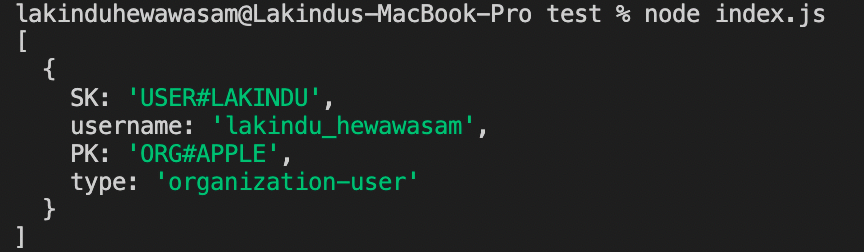
Fetching the organization and its users
Omit the sort-key predicate to read the complete item collection:
This constructs a combined application response. It does not repeat the organization's columns on each user as a relational join might. The array accumulation is suitable only for a bounded collection; paginate users in the application when an organization can have many members.
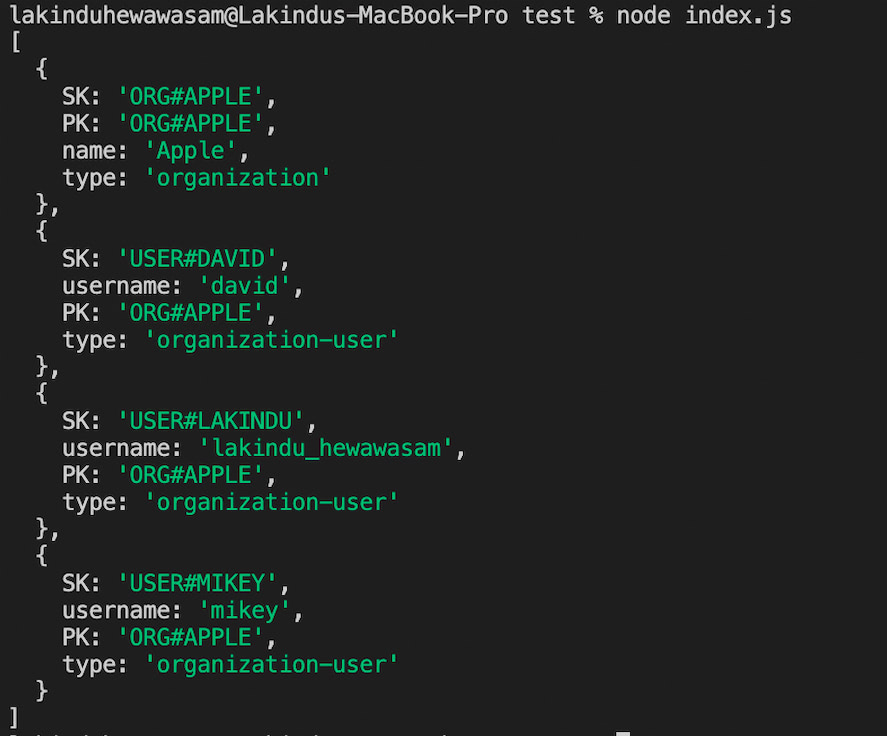
A Query request evaluates at most 1 MB before filtering. Even a well-designed collection can require several calls, so a single access pattern is not necessarily a single network request. The pagination guide covers streaming results and continuation cursors.
Application-side joins across tables
Suppose user profiles live in Users and organization memberships live in another table. First query the membership keys, deduplicate the referenced user IDs, then fetch the corresponding profiles and assemble the response by ID. Avoid issuing a separate unbounded sequence of reads for every membership.
BatchGetItem can retrieve known primary keys from multiple tables in one call. It accepts up to 100 items with a 16 MB response limit, may return partial results, and does not preserve requested order. Retry UnprocessedKeys with backoff, include key attributes in projections, and map returned items by their full keys. Missing records must be handled explicitly; they are omitted from the response. See the BatchGetItem reference.
BatchGetItem does not discover related keys and is not an atomic multi-item snapshot. Strong reads can improve individual read freshness, but they do not make the lookup and subsequent batch one transaction. If an invariant requires an atomic read of a known set of items, evaluate transactional reads and their constraints instead.
Many-to-many relationships and reverse lookups
If a user can belong to multiple organizations, store a membership item for each relationship. Keep canonical user details separately, or copy selected values onto memberships with an explicit synchronization policy.
For example, membership items can keep PK = ORG#123 and SK = USER#456. A GSI that uses SK as its partition key and PK as its sort key can read all memberships for USER#456. Define the projection so the index includes the fields that reverse lookup requires. A GSI is an additional stored index and consumes storage and write resources; it is not a free join over two attributes.
This is an adjacency-list approach, described in AWS's many-to-many modeling guide. It supports known edge lookups. Arbitrary multi-hop traversals can still need repeated reads and may fit a graph database better.
Denormalization, updates and consistency
Copying an organization's display name onto each membership can eliminate a second read, but a rename now affects multiple records. Decide whether the copied name is a historical snapshot or a current value. Those are different data requirements, not merely different update strategies.
For current copies, synchronous updates need a bounded write set and failure handling. An asynchronous read model can use change events to update copies, but consumers must tolerate retries and a period of staleness. GSIs are also eventually consistent, so a newly added membership may not immediately appear through the reverse index.
DynamoDB does not enforce foreign keys or cascading deletes. Define behavior for an organization deleted while memberships remain, a missing user profile, and partial failures during membership creation. Conditional writes and transactions can protect bounded invariants; they do not replace lifecycle design.
Performance and choosing an analytics engine
Reading one targeted item collection can avoid a series of application lookups. That is a useful reduction in round trips, not proof that DynamoDB is universally faster than an SQL database. Measure returned bytes, capacity consumed, pagination and hot-key behavior for the actual workload.
Start from the reads your application must serve. Design selective keys, bound collection growth, and use indexes for additional access patterns when their storage and write costs are justified. A filter that discards most candidates is a signal to revisit the model. A large organization concentrated behind one hot key can need a different distribution strategy, which changes how its results are gathered.
For reporting across arbitrary entities, export to S3 for Athena or use a suitable zero-ETL analytics integration. Those engines perform the join outside DynamoDB. Amazon EMR with Hive can also join mapped DynamoDB tables, as the AWS Hive examples demonstrate; reads against live source tables need a capacity budget. The DynamoDB SQL guide compares operational PartiQL with analytics options.
Frequently Asked Questions
Can DynamoDB do joins?
Can DynamoDB store relational data?
Does single-table design return a joined result?
How does DynamoDB handle many-to-many relationships?
Can BatchGetItem join two tables?
Dynobase is a Professional GUI Client for DynamoDB
Start your 7-day free trial today
Product Features
DynamoDB Tools
- SSH GUI Client
- Chat With Cloud
- MongoDB GUI Client
- AWS Cost Monitoring
- DynamoDB Query Builder
- DynamoDB Code Examples
- DynamoDB Node.js Queries
- DynamoDB JSON Converter
- DynamoDB UUID Generator
- DynamoDB Local Admin GUI
- DynamoDB Pricing Calculator
- DynamoDB Single-Table Design
- Best DynamoDB GUI Clients
- Dynobase vs DynoTable