
Working with DynamoDB items, columns and attributes
Written by Andrea Perera
Last updated: October 23rd, 2026
A DynamoDB attribute is a named value within an item, similar to a field in a JSON document. Items in the same table can have different non-key attributes, so adding a “column” means writing a new attribute on selected items rather than altering a table-wide schema. The table's primary-key attributes are required and have fixed types; other attributes can be added, changed or removed with update expressions.
DynamoDB tables, items and attributes
| DynamoDB term | Relational analogy | Important difference |
|---|---|---|
| Table | Table | Declares keys, not every possible field |
| Item | Row | Can have a different set of non-key attributes from other items |
| Attribute | Column value or field | Belongs to an item; can contain a nested document |
| Primary key | Primary key | Is a partition key alone or a partition key plus sort key |
DynamoDB is a key-value and document database, not a columnar analytics database. A GUI may display attributes as columns, but that display does not impose a uniform schema on all items.
For example, a Book item can have BookAuthor, BookTitle, isSold and a details map, while another book has no isSold field. Missing, null and empty values are different states, not interchangeable representations of the same thing.
Attribute types and limits
DynamoDB supports scalar types (String, Number, Binary, Boolean and Null), document types (List and Map), and sets of Strings, Numbers or Binary values. Lists preserve order and can mix types; sets contain unique members of one type and are unordered. The data types reference covers representations and SDK conversion.
An item, including attribute names and values, must fit within 400 KB. There is no separate fixed number of ordinary attributes per item. Maps and lists can nest up to 32 levels. Long attribute names count toward storage and capacity calculations, so use clear, reasonably short names.
Empty Strings and Binary values are valid for non-key fields. Empty lists and maps are also valid, but empty sets are not. Primary-key and index-key attributes must be top-level String, Number or Binary values matching their schema; String and Binary key values cannot be empty.
AttributeDefinitions in table creation is not a catalogue of every field your application might store. It declares the types of table and index key attributes. Adding an ordinary field such as isSold does not require UpdateTable or a schema deployment.
Set up the example table and client
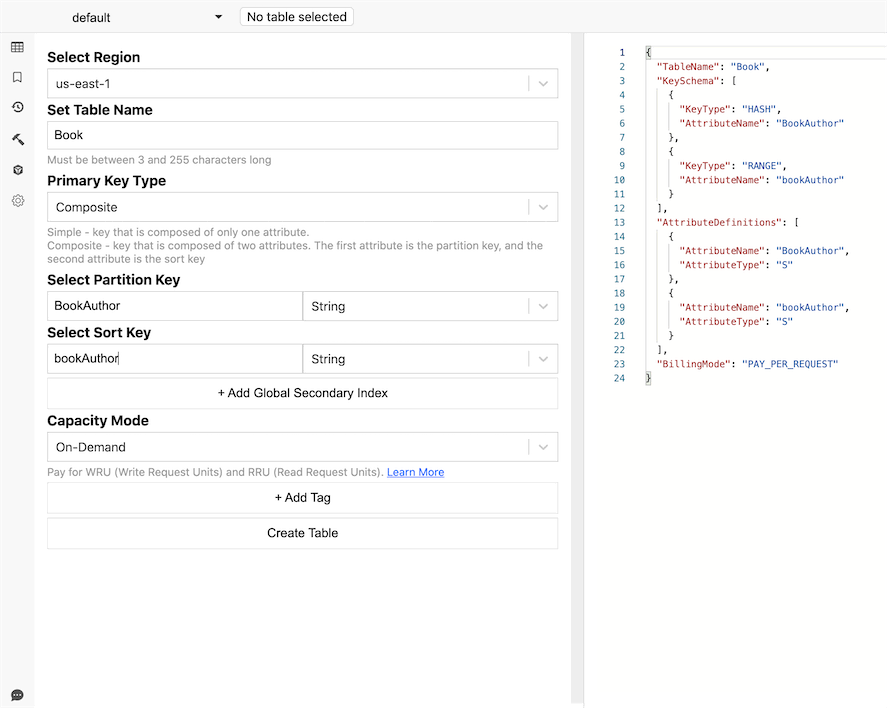
The examples use a Book table with String partition key BookAuthor and String sort key BookTitle. This table has a composite primary key, so every single-item update includes both attributes. The sort key is optional for DynamoDB tables in general, but it is required by this example schema.
Create that table using your existing infrastructure workflow or the table creation guide. The historical screenshot below illustrates defining the two key attributes; the current application layout may differ.
Use AWS SDK for JavaScript v3 with its document client and the default credential provider chain:
Configure credentials through your AWS profile or execution role. The examples do not embed access keys. They assume the book already exists; the update conditions prevent accidentally creating a partial item if it does not.
Add an attribute to an existing item
SET adds an attribute or replaces its current value. Store isSold as a Boolean if it represents a true/false flag:
Without a condition, UpdateItem can create a new item at the supplied key. To add a default only when a field is absent, use SET #sold = if_not_exists(#sold, :sold). That preserves an existing value, including explicit null; it does not validate that the old value has the type your application expects.
Java 2.x equivalent
For Java applications, use the current SDK's UpdateItemRequest and expression fields instead of the old AttributeValueUpdate API. This example is a complete class and uses the same table keys:
Rename an attribute atomically
DynamoDB has no table-wide rename-column operation. For a non-key attribute on one item, copy its value and remove the old attribute in one atomic update:
The right-hand value is evaluated from the pre-update item, so this preserves its value and type. The condition avoids copying a missing source or overwriting an existing destination. If both fields exist, decide which is authoritative instead of silently discarding one. AWS documents the evaluation order in update expressions.
You cannot rename a primary-key attribute with this operation. That changes the table schema and requires a migration. Renaming a non-primary attribute used by a GSI also needs an index migration plan, because removing that field can remove index membership.
Remove an attribute from an existing item
Use REMOVE, not DELETE, to remove an entire attribute. In update expressions, DELETE removes selected members of a set.
Removing an absent attribute from an existing item is harmless. Setting it to null instead would retain the attribute with the Null type. That distinction matters for attribute_exists, sparse indexes and application defaults.
Add an attribute to all items
There is no single DDL command to fill an attribute across the table. Enumerate the relevant item keys and update each item. Use a key query when you know the target collection, or a paginated scan for a table-wide migration.
This example adds createdDate only where it is missing. The value is an illustrative migration default, not a claim about when an existing record was originally created:
Projecting keys makes responses smaller, but does not make the scan's read-capacity cost proportional only to those keys. The sequential updates keep the example simple; production jobs can use bounded concurrency, backoff, saved progress and reconciliation. A scan is not a snapshot of a changing table, even with strong reads.
Deploy writers that populate the new attribute before backfilling, then validate coverage. If the value must represent historical creation time, derive it from a trusted source instead of substituting the migration date. BatchWriteItem cannot perform updates or per-item conditions, so it is not a direct substitute for this loop.
Remove or rename an attribute across all items
Reuse the paginated key loop with the single-item REMOVE or atomic rename expression. For a rename, consider a staged deployment: readers accept both names, writers move to the new name, the backfill handles old records, and old-name support is removed after verification.
Treat condition failures according to their meaning. A missing old field may already be migrated; a present destination may be a conflict that needs inspection. Do not catch every failure and report the migration as complete. Store failed keys for retry or review.
Use conditions or item versions if concurrent writers could recreate a removed field or change the source during migration. A single item update is atomic; a table-wide sequence of updates is not. The item update guide covers expressions used by these operations.
Query one or two attributes
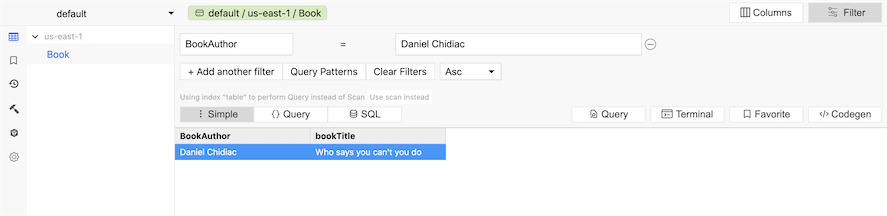
A Query must include equality on the chosen table or index partition key. The sort-key condition is optional, even for a composite-key table. This request constrains both table key attributes:
For two ordinary non-key attributes, you cannot simply place both in KeyConditionExpression. Query a useful key range and filter, create a suitable secondary index, or scan for an infrequent inspection. Filters discard data after it is read, so they do not make a broad read cheap.
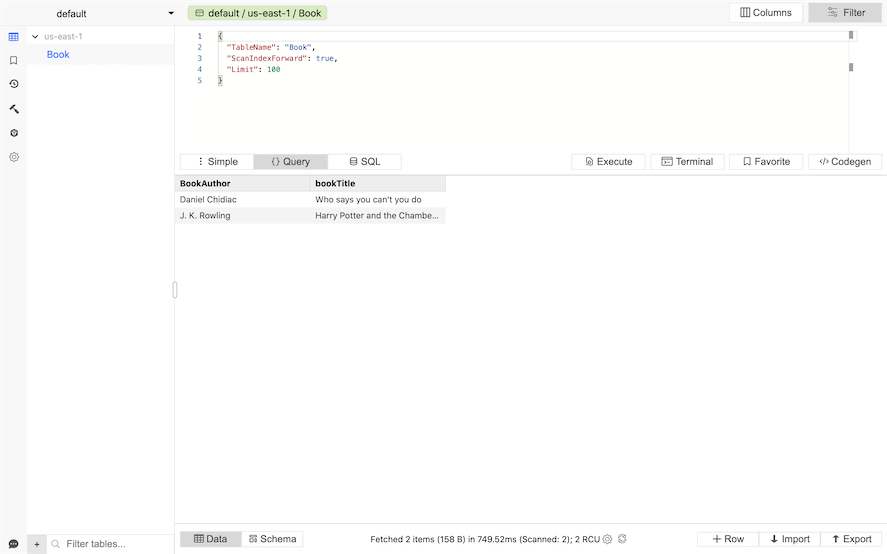
These historical Dynobase views illustrate selecting keys and adding filters. Their controls may differ from current releases; the API behavior above is what determines the read's scope and cost.
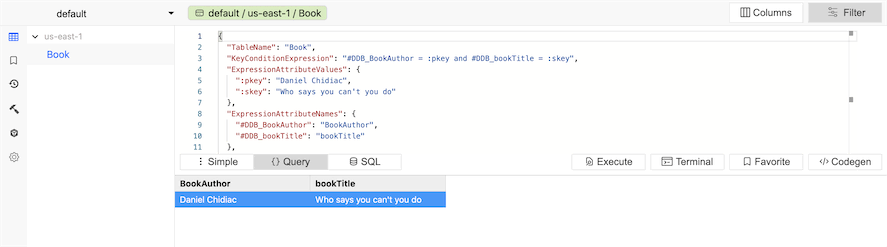
Query and update nested attributes
Nested map and list paths work in filter, projection, condition and update expressions. They cannot be table or index key attributes. To query directly by a nested field, maintain a suitable top-level scalar copy and index that attribute.
For example, this query selects an author's books and then filters on details.language:
A path such as details.language means a child field. An attribute literally named details.language instead needs one alias mapping to the complete name. When updating a nested path, its parent map must already exist; initialize the map deliberately rather than overwriting its siblings. See the AWS attribute-path reference.
Scan and return all attributes
A table scan returns all item attributes by default. It evaluates at most 1 MB per request, so iterate until LastEvaluatedKey is absent:
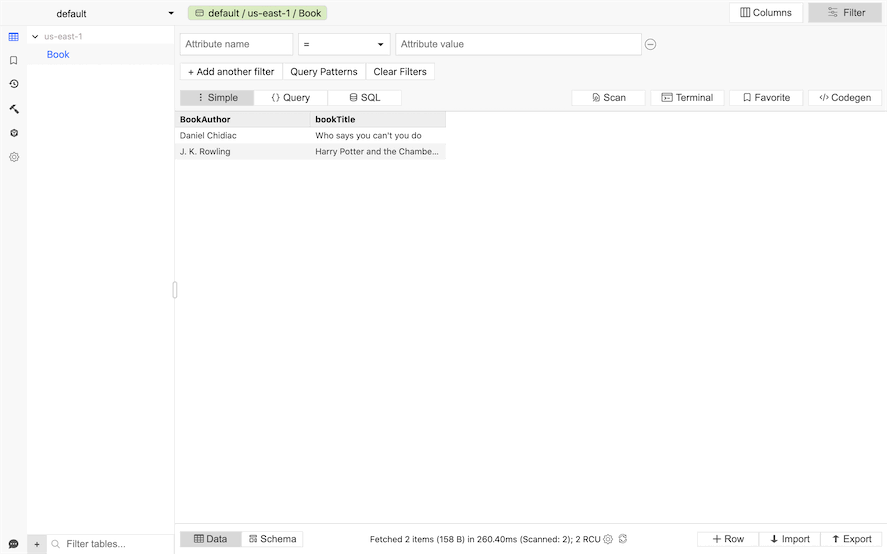
Use this for inspection or planned batch work, not as a default application lookup. If you add a filter, continue even through empty pages with a cursor. A GSI scan is different: it can only return attributes projected into that index.
List the attributes in a table
DescribeTable describes key schemas and settings, not every field found in every item. To discover non-key attributes, inspect item data and collect the observed names and types. Sampling can miss rare fields; a full scan is more complete but costs reads and still reflects a changing dataset.
Dynobase Schema Explorer helps inspect the shapes present in real data. Use discovery to inform application validation, not as proof that every item follows one schema. Expression aliases for awkward names are covered in the reserved-words guide.
Frequently Asked Questions
What is an attribute in a DynamoDB table?
Does DynamoDB have columns?
How many attributes can a DynamoDB item have?
Can I rename a DynamoDB attribute?
Can I query a nested attribute in DynamoDB?
How do I add an attribute to every DynamoDB item?
Dynobase is a Professional GUI Client for DynamoDB
Start your 7-day free trial today